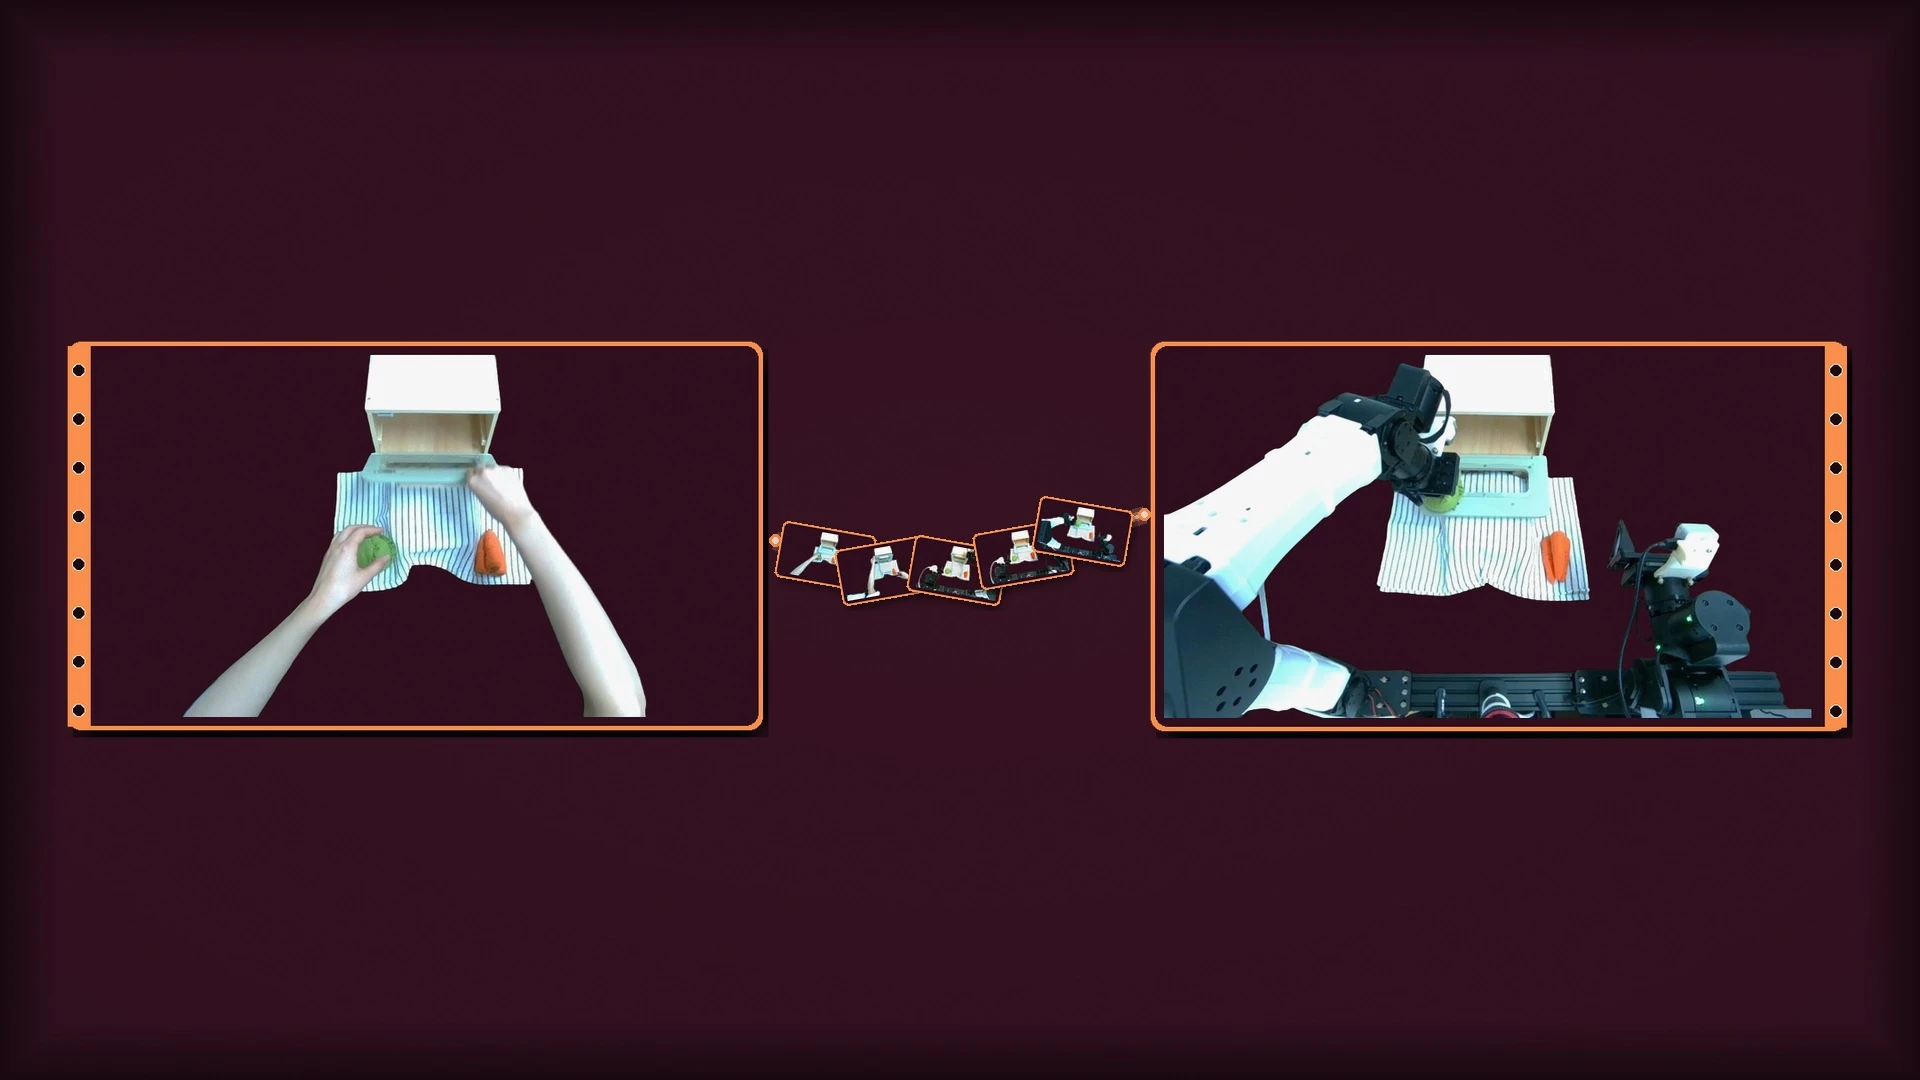
NVIDIA Proposes ThinkWorld to Train VLAs on Unannotated Human Videos via Chain-of-Dynamics and Imagined Futures
NVIDIA and KAIST introduce ThinkWorld, a vision-language action framework that leverages chain-of-dynamics reasoning and imagined future states to extract training signals from unannotated human videos for robot policy learning.