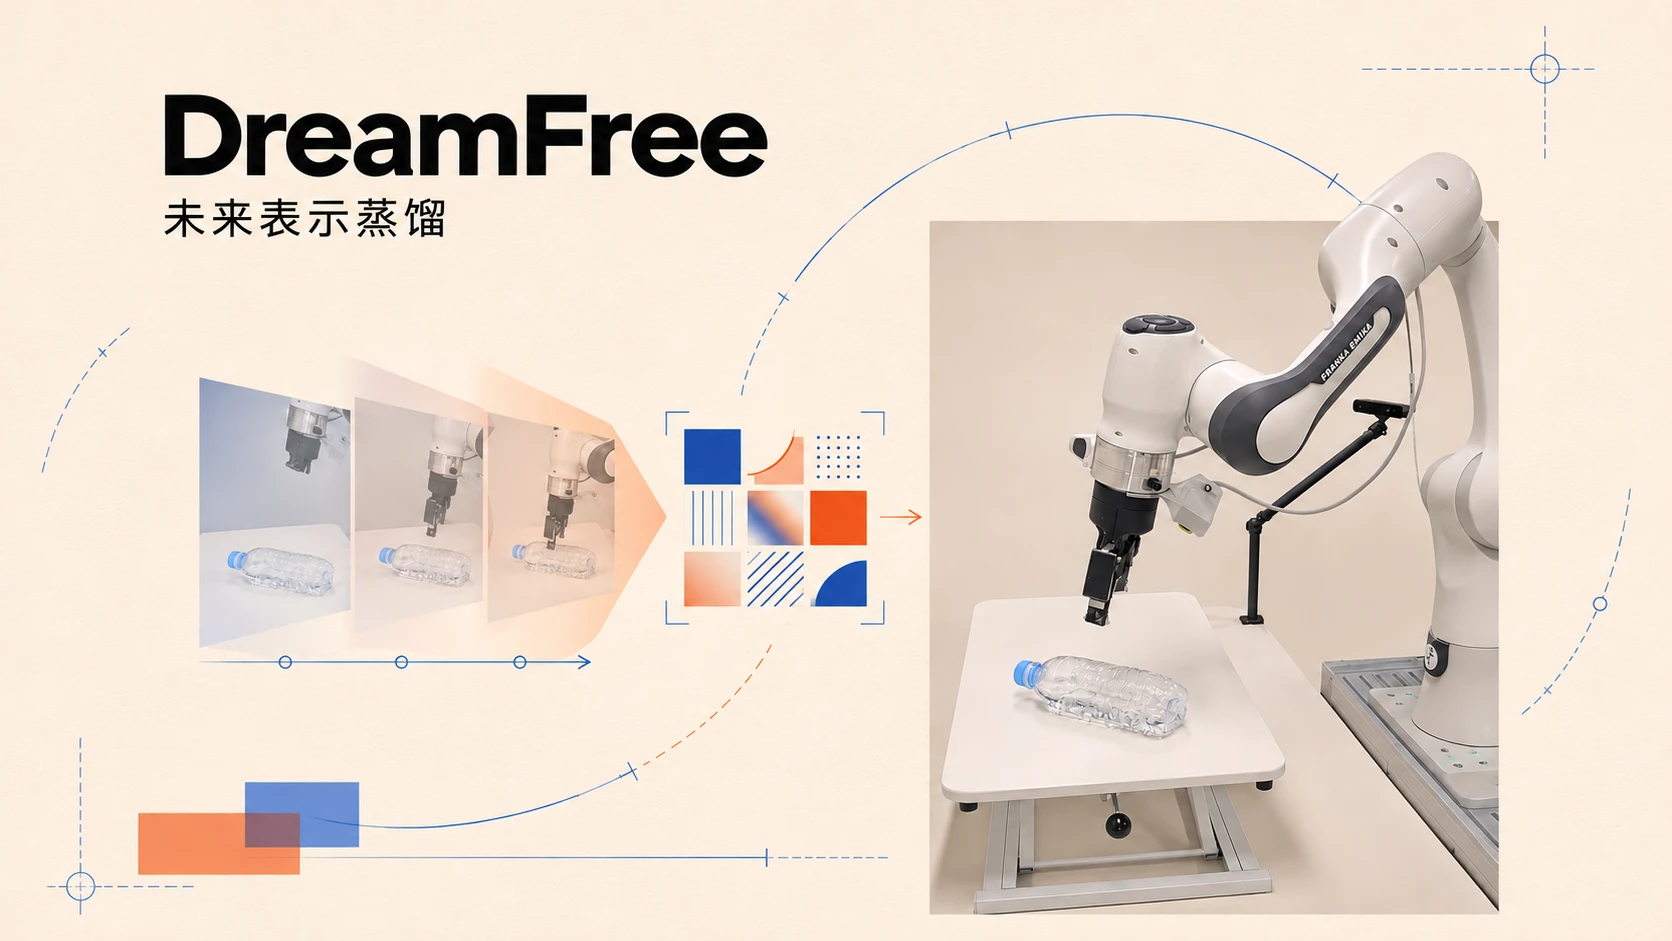
DreamFree Distills Future Representations for Imagination-Free Robot Control
KAIST researchers introduce DreamFree, a world-action model that distills predictive capabilities from a video diffusion model into a visual encoder. This enables robots to output actions from a single current frame, bypassing the computationally expensive step of generating future video sequences during deployment.