Fudan Team Bridges Active Perception and Vision-Language-Action Models to Overcome Viewpoint Shifts
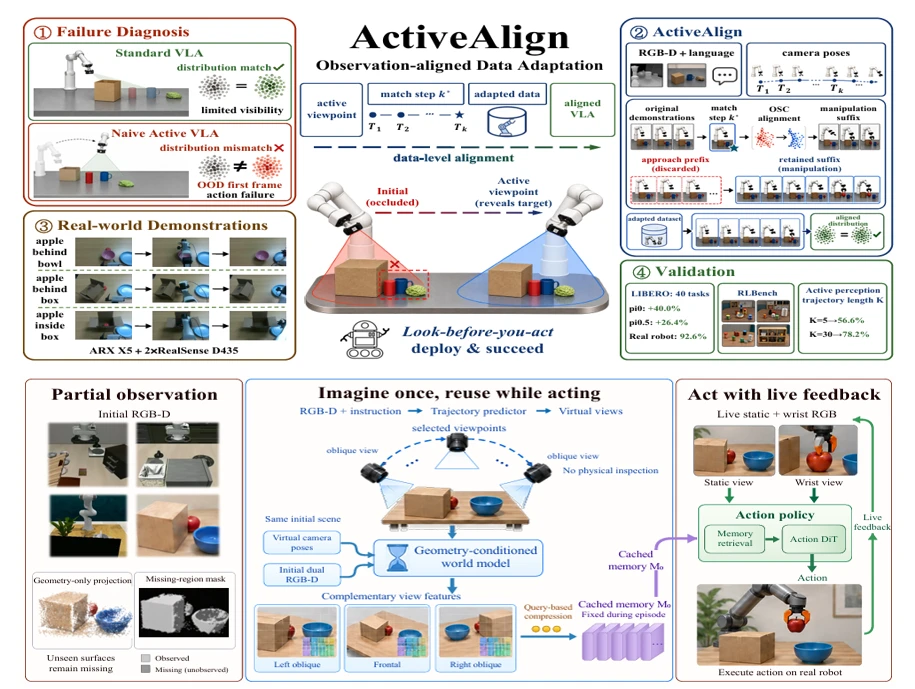
Two papers from Fudan University introduce ActiveAlign and AWAM, which align training data and representations with active camera movements to prevent distribution shifts in vision-language-action models when robots adjust their viewpoints to overcome occlusions.