
Robots Are Starting to 'Eat Data': From Indian Data Factories to the Hidden Supply Chain of Billion-Dollar Humanoid Robots
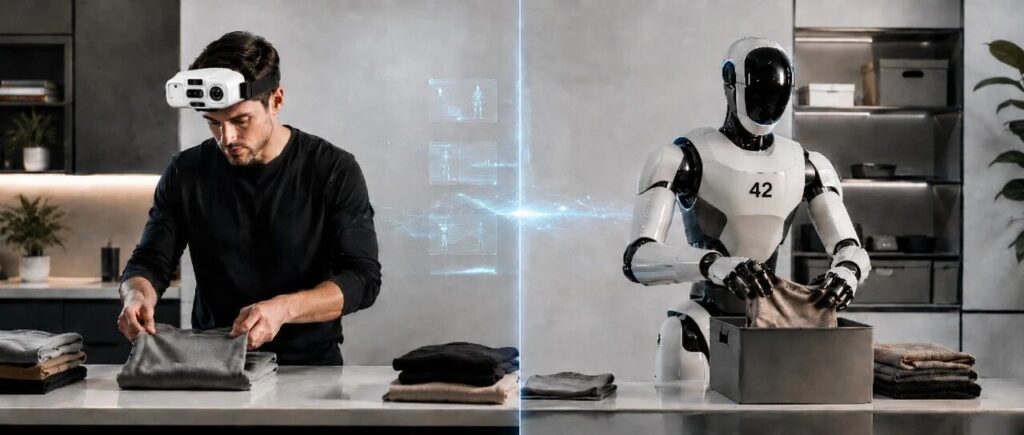
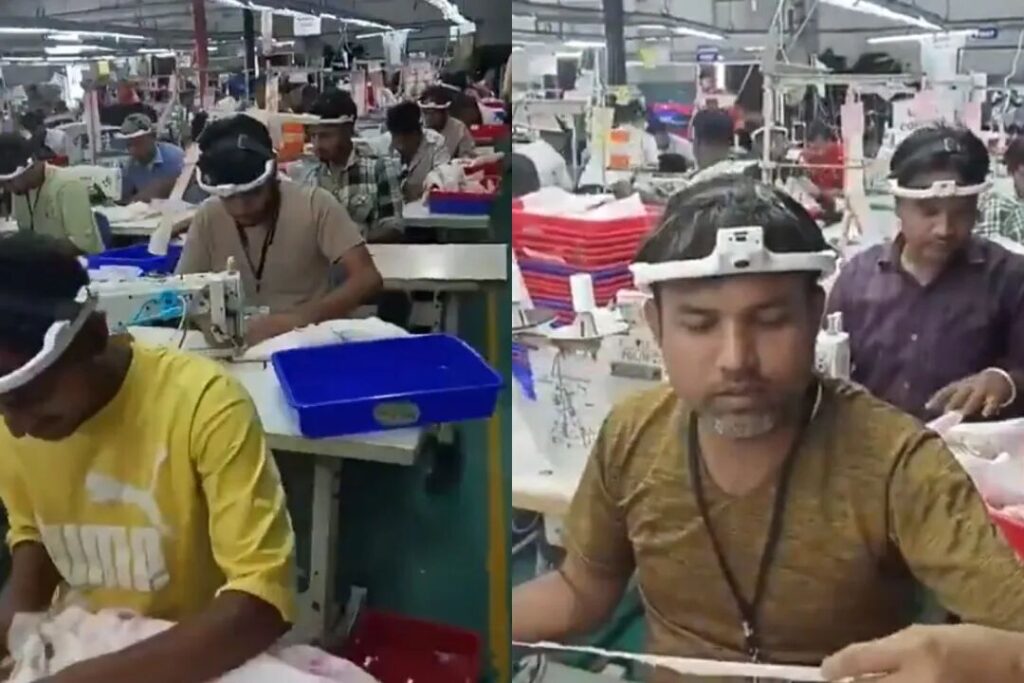
In a garment factory in India, workers are organizing fabric as usual, but this time they have cameras mounted on their heads to capture first-person point-of-view footage of their work.
After processing, these videos will become data assets and be sold to embodied AI companies that need large volumes of data to train robots.
This type of business is accelerating into a new industry chain starting this year, driven by the biggest bottleneck currently facing the embodied AI sector: data.
"The demand has clearly picked up this year," an industry insider involved in robot data collection told 42 Hertz. The European and American robot companies his team serves are heavily purchasing human work data. His team now has nearly 100 collectors participating in robot training data production, stably generating thousands of hours of first-person human video data per month.
Collectors must follow standard procedures to complete tasks such as folding clothes, kitchen organization, and object grasping, while wearing head-mounted cameras; for some tasks, data gloves are also used to record more detailed hand movements.
"Previously, the industry focused on models and hardware, but now more people are asking whether data supply can be stable."
People are increasingly realizing that the biggest bottleneck preventing breakthroughs in model capabilities is insufficient data scale.
Against this massive data gap for embodied models, the new business of data collection is rapidly taking shape.
Why Are Robots Starting to Face a Data Shortage?
If we rewind three years ago, robots resembled traditional automation industries.
Most robots were fixed in factories with highly structured workflows: welding, material handling, spraying, and assembly. They did not need to understand complex environments or learn generalization capabilities; they only needed to repeat actions along predefined trajectories.
Today, many companies aim beyond traditional industrial robots. From Tesla and Figure to PI, the industry is attempting to train robots like large models, endowing them with general-purpose capabilities.
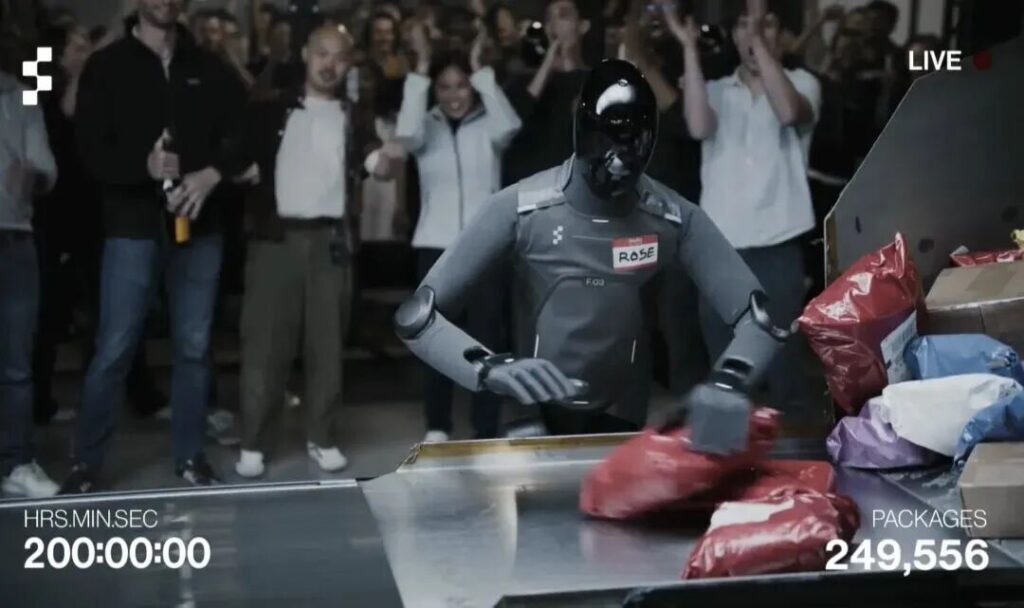
So the path taken by embodied models is increasingly resembling that of Large Language Models (LLMs), but it is far more difficult, especially in the data domain.
For LLMs, the internet itself is a natural goldmine of data. Web pages, books, academic papers, code repositories, and other resources accumulated over decades constitute massive training corpora. Model companies typically only need to solve how to filter and clean this data; they rarely need to create data from scratch.
But embodied models are different. They face the physical world—a data desert. Robotic motion data does not appear out of thin air. Although there are many videos of human work on the internet, the volume of such data is still insufficient for robots, and the overall quality is not high enough.
If you say an LLM was born in a library, a robot is more like being born in a desert.
So while AI has entered the stage of computing power competition and inference optimization, the embodied intelligence industry remains trapped by the most basic question: Where does the data come from?
This is why, despite increasingly complex model architectures, robots are still far from truly entering homes and complex scenarios.
It is because the models lack sufficient real-world experience.
Previously, Figure founder Brett Adcock offered a very direct viewpoint: 'If I snap my fingers and the massive amount of data we really need could be stuffed into the Helix model, we would immediately crack general-purpose robotics.'
But the question is, where does the data come from?
How Is One Hour of Data Produced?
In February this year, a research finding began to excite the industry.
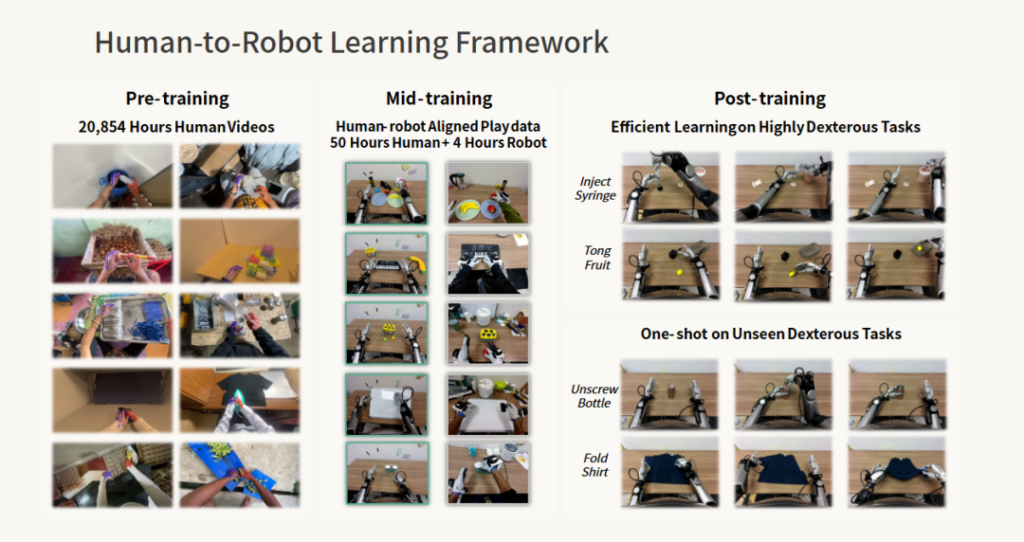
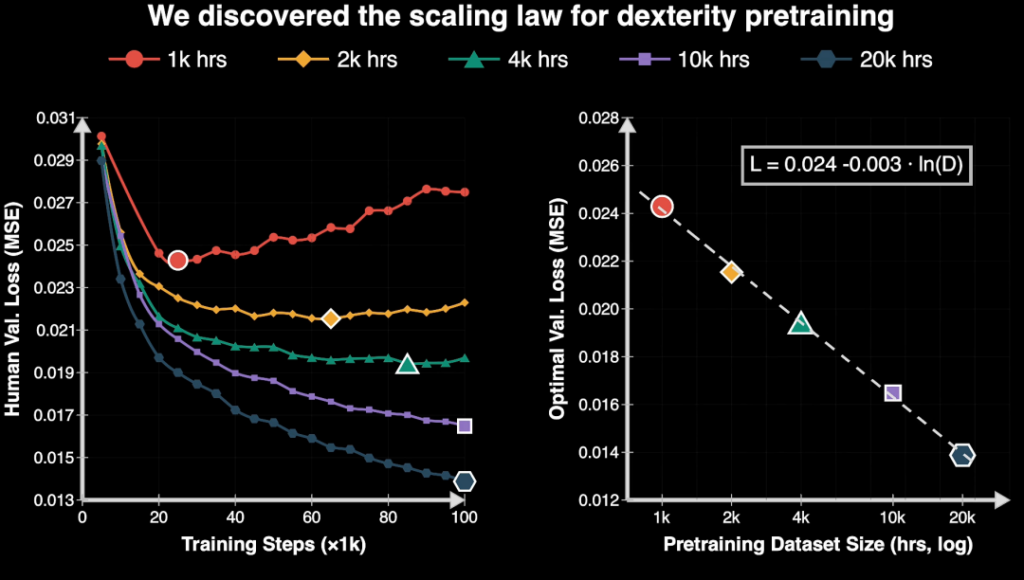
The NVIDIA team released EgoScale. By pre-training a model on over 20,000 hours of first-person human videos with motion annotations, and then fine-tuning it with a small amount of robot data, the Sharpa Wave 22-DOF dexterous hand was able to complete tasks such as twisting bottle caps and folding clothes.
More importantly, the study found that as the scale of human data increases, model performance improves steadily, and this improvement is predictable.
This research is crucial for the embodied AI industry. After all, a scalable data pathway means that robot capabilities can enter a positive cycle—"more data leads to stronger capabilities"—similar to large language models.
For a long time, the embodied AI industry has been plagued by anxiety: even with increased investment, improvements in model capabilities remained highly unpredictable. This was largely because real-world data was scarce and prohibitively expensive to acquire, discouraging significant capital allocation in the data sector.
However, EgoScale has demonstrated something crucial: at least for human first-person data (Ego Data), scale does indeed yield consistent returns for dexterous hand manipulation tasks.
Meanwhile, an increasing number of robotics companies are adopting a pathway that combines massive amounts of human data with a smaller set of robot-specific data.
Human first-person videos instruct the model on how humans accomplish tasks, while robot data teaches the model how its own body should operate.
Thus, the primary value of Ego Data lies in serving as easily scalable prior knowledge, enabling robots to first understand the physical world before adapting through limited real-robot data.
Consequently, the new industrial chain centered around Ego Data has begun to accelerate significantly this year.
Humans wear a camera on their head or chest while performing specific tasks—such as folding clothes, organizing kitchens, or sorting packages—and the camera records first-person video footage of their work.
From a certain perspective, humans themselves are the world's most mature general-purpose robots. When entering a kitchen, people naturally judge what to do first and what to do later; when space is tight, they free up another hand. When handling fragile items, they subconsciously adjust their grip strength.
Behind these seemingly instinctive actions lies a vast amount of spatial understanding, task planning, and object interaction logic.
In the past, robots had almost never systematically acquired these experiences.
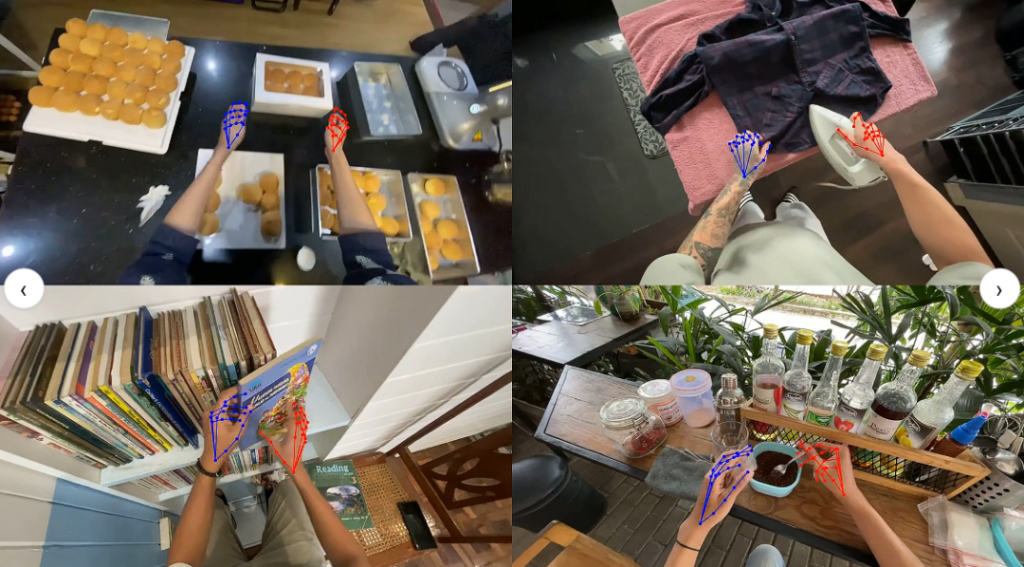
But Ego Data does not simply film videos at random, nor is capturing video at scale the greatest challenge. The key lies in transforming these experiences into data products that can be truly utilized by models.
A practitioner who began accelerating their layout of Ego data earlier this year told 42 Wave that true data collection usually begins with a task specification document sent by the client.
These documents do not simply state 'collect kitchen organization data'; rather, they often contain explicit regulations:
What is the task type? Are both hands required to fully enter the frame? Should the camera be positioned on the head or the chest? Is it allowed for movements to be interrupted? How many environmental variations are needed? Are failure samples required? Does the final delivery format need to be compatible with the training framework?
For example, when organizing a kitchen, the client might require: continuously completing multiple steps such as opening cabinet doors, locating containers, making space, picking and placing items, and closing the doors, without skipping frames or experiencing severe occlusion.
In a sense, this is more like producing an industrial product; the entire data collection process is far more 'factory-like' than imagined.
In some data collection centers, collectors take turns entering prepared kitchens, cloakrooms, and shelf areas, repeatedly executing tasks according to unified SOPs.
Some are responsible for folding clothes, others practice grasping items of different sizes repeatedly, while others specialize in collecting data on kitchen organization and transport.
The same action often needs to be repeated by people of different heights, dominant hands, and operational habits, attempting to exhaust all possible scenarios in the physical world, since robots ultimately face a complex real world rather than a single standard answer.
When putting a cup into a cabinet, some first make space, others switch hands, and others prefer to open the door first; these subtle differences precisely constitute part of the robot's generalization capability.
Therefore, for many embodied models, what they need to learn is the logic of 'how humans typically complete this task.'
Compared to real-machine data, this type of data is easier to mass-produce. Faced with huge industry demand, as long as scale is maintained and labor costs are low, it has a foundation for profitability and relatively easy cash flow generation.
However, if the data does not meet client requirements, it must be reworked. The amount of data that truly passes final client acceptance is far less than the original recording duration; therefore, the effective duration directly usable for training is what matters most.
From this point onward, the industry has begun to show increasingly clear stratification. Because different types of data vary greatly in value, a comprehensive analysis from perspectives such as cost and value can roughly form a "data pyramid."
Vast Value Differences Among Different Types of Data
At the bottom of the "data pyramid" lies internet data, which carries almost no collection costs while also boasting significant scale.
Robots can learn from this what objects look like and the general layout of a kitchen. However, the limitations are obvious: it can only help robots "know," making it difficult to help them "do." The real challenges of the physical world lie in actions—friction, weight, material variations, spatial constraints, and collision risks—which cannot be mastered through ordinary video alone.
Higher up is human data, with Ego Data being one of the most critical components. It tells the model how humans operate from a first-person perspective. This type of video data can be used on a large scale for pre-training, as demonstrated by EgoScale.
Yet, robots ultimately still need to solve the problem of how their own bodies should move. For example, while a human hand can easily twist off a bottle cap, a robot may fail repeatedly.
Thus, the perception data provided by data gloves is becoming increasingly important. Ordinary Ego Data can only tell the model what a person saw and what tasks were completed. However, robots ultimately need to know when to increase force and when to relax.
These subtle movements are difficult to infer solely from video, so more and more companies are beginning to attempt aligning hand motion capture, pose estimation, joint trajectories, and visual data.
Video provides spatial understanding, gloves provide movement details, and teleoperation data from real machines further helps robots understand how their own bodies should execute actions.
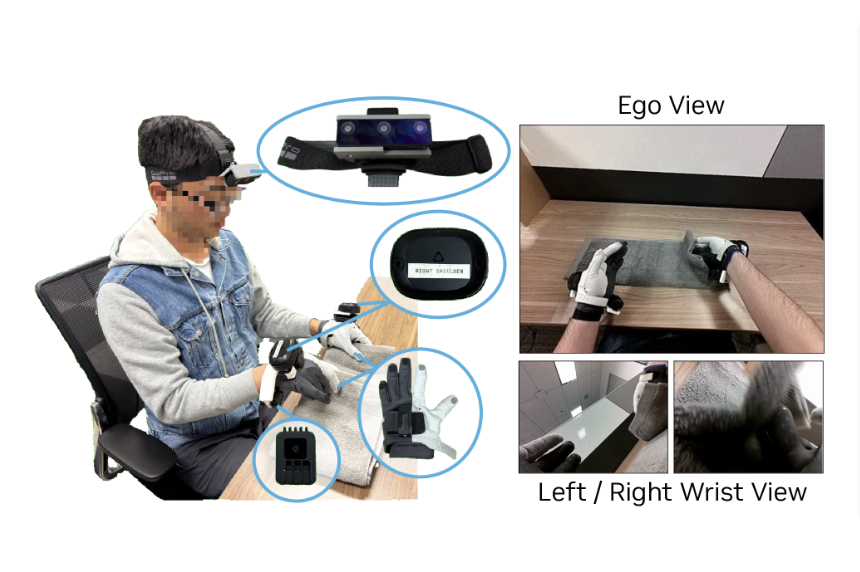
However, there is still a very practical problem in the industry: standards for data gloves remain highly inconsistent. Different devices vary significantly in sampling frequency, joint definitions, precision, and action representation. How to stably map human movements to different robot bodies remains a significant bottleneck.
Therefore, if one does not wear data gloves and only uses head-mounted cameras for recording, the price of Ego Data is not particularly high. But once data gloves are added, the cost rises rapidly.
Moving up the pyramid, we have simulation data. Through digital twin environments, robots can train at high speeds in virtual worlds, repeatedly experiencing millions of grasps, navigations, and obstacle avoidance maneuvers. Data that takes a month to collect in the real world might be generated in just a few days within a simulation environment.
However, simulation is ultimately not the real world. Although it offers large volumes and low costs, it is difficult to fully replicate accidental factors such as friction, material variations, and reflections found in reality. This is often referred to in the industry as the "Sim-to-Real Gap." Robots that perform well in simulation often see their capabilities significantly diminished once they enter the real environment.
At the top of this pyramid lies the highest-quality, most expensive, and scarcest real-robot data. This is primarily obtained through teleoperation, where human operators control robots to complete specific tasks while the robot simultaneously records visual inputs, motion data, control signals, and sensor states.
Unlike human-centric data, real-robot data is naturally situated within the robot's action space, eliminating the need for models to struggle with mapping human movements onto robotic bodies. Additionally, real-robot data includes autonomous operational data generated during application; however, since robots are not yet widely deployed at scale, the resulting data remains scarce.
A key challenge with real-robot data is its extremely low production efficiency. Scaling up data volume requires deploying more robots and operators, alongside high costs for facilities and equipment wear and tear, which rapidly drives up prices.
According to industry insiders, pricing varies significantly: basic Ego Data typically costs only tens of yuan per hour, whereas robot body data involving teleoperation often rises to hundreds or even thousands of yuan per hour.
During the training of different vendors' robot models, various layers of the data pyramid play distinct roles. Consequently, the industry has seen the emergence of upstream data companies specializing in different areas, such as simulation and first-person human-view data.
Who is Trading This Data?
When a massive industry emerges, the earliest beneficiaries are often the upstream "water sellers".
The same is true for the Embodied AI industry. Over the past year or two, a large number of robot startups have emerged globally, with talent from various industries flocking to this field.
Almost every day, new companies announce that they have completed financing rounds. In China, companies with valuations exceeding 10 billion RMB are becoming increasingly common, and some have even embarked on the path to an IPO. Looking abroad, Figure reached a valuation of $39 billion after completing its Series C funding last year, ranking first among humanoid robot companies.
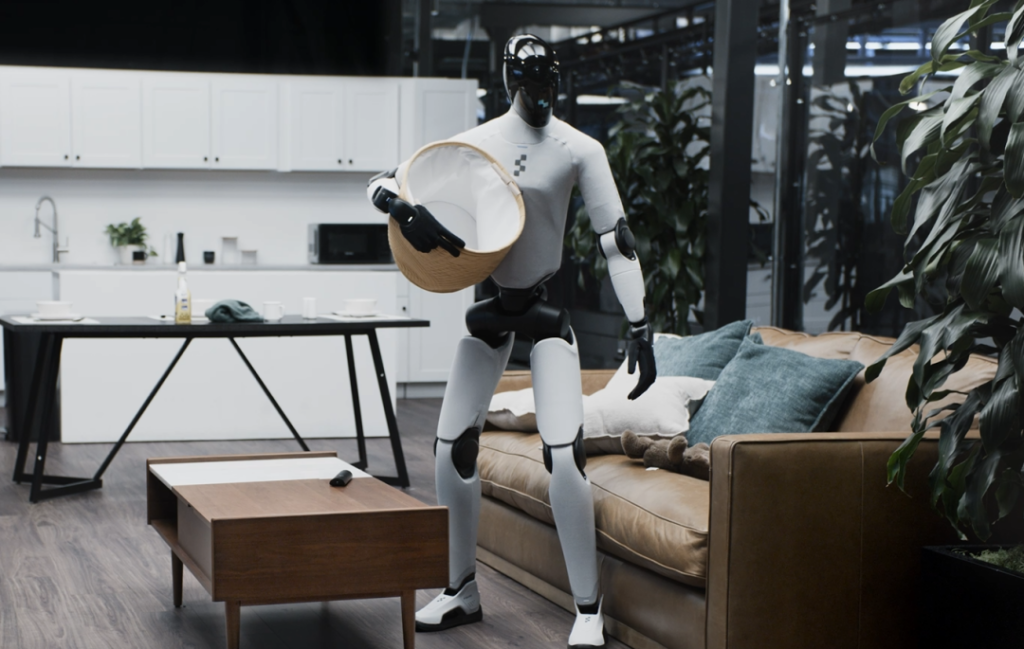
Everyone wants to build general-purpose humanoid robots, and all of them require massive amounts of data. Meanwhile, due to the continuous influx of capital, the entire sector remains well-funded.
Therefore, behind these companies with strong data needs and ample R&D funds, more and more "water sellers" in the upstream of the robotics industry have emerged, gradually forming a data production chain for the robotics industry.
Moreover, as the industry develops, these upstream companies have begun to form distinct layers around the data required for robot training. Based on the current industry structure, players can roughly be divided into five categories.
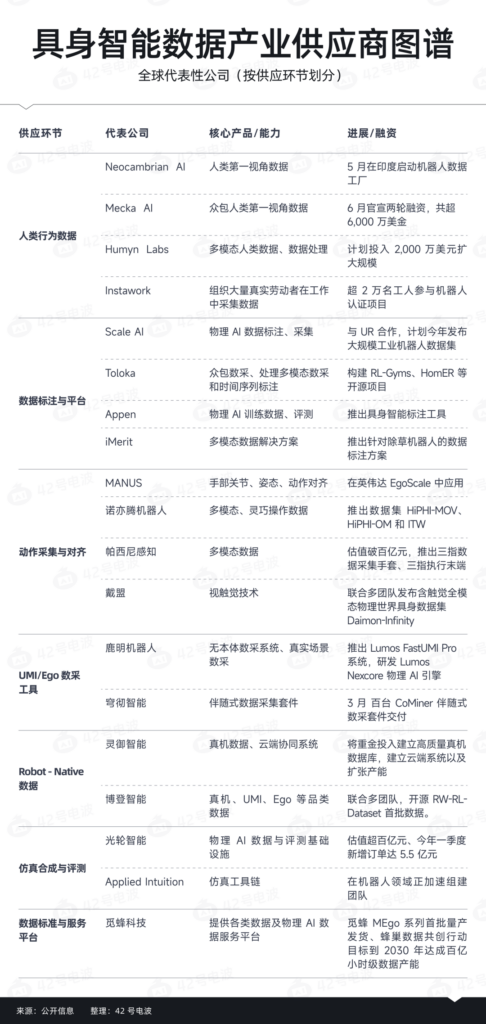
The first category is low-cost data factories. The focus of data collection is Ego Data. In countries such as India and Thailand, an increasing number of teams are organizing low-cost labor to build data collection networks.
For instance, a startup called Neocambrian AI has recently launched a robot data factory project in India to collect human motion data for embodied models, particularly Ego Data. Its founder specifically highlighted that India's vast labor force is a significant advantage for developing physical AI datasets.
Data collectors wear head-mounted cameras and motion capture gloves to complete tasks according to workflows. The backend team then cleans, annotates, and inspects the data before delivering it to robotics companies.
From a business model perspective, they resemble early-stage data annotation companies that served large language models; however, instead of labeling text, images, and audio, they are now producing experiences from the physical world.
An industry insider told us that overseas client demand has noticeably increased over the past year. Especially among European and American robotics companies, "they have clearer specifications for data and know exactly what they need."
Robotics data collection is not as simple as "recording videos." Many clients actually require a set of data ready for direct integration into training pipelines, including time series, multi-view footage, motion trajectories, sensor states, hand poses, environmental metadata, and final formats adapted for training.
During this process, more and more companies have realized that relying solely on low-cost labor makes it difficult to build long-term barriers to entry. For these low-cost data factories, the ultimate competitive barrier will depend on how easily the delivered data can be directly utilized.
The problem is also very realistic: this business is inherently prone to commoditization. If one team can do it, another theoretically can too. As prices become increasingly transparent, profit margins are often squeezed.
Therefore, low-cost delivery capability is their greatest advantage but may also become their ceiling.
The second category is the motion acquisition and alignment layer. Rather than simply collecting video, these players aim to solve the problem of "how motions are truly understood by machines." For them, the emphasis is not just on data volume but more critically on motion representation.
Examples include data gloves, motion capture, hand tracking, motion retargeting, and manipulation acquisition interfaces.
The real difficulty for robots often lies not in visual understanding but in execution. Even when performing the same task, such as grasping a cup, different robotic dexterous hands vary in degrees of freedom, joint structures, and force-control capabilities.
This raises a key question: How can human motions be stably mapped to robots with diverse physical bodies?
Consequently, an increasing number of companies are focusing on motion retargeting. In this process, video data informs the robot of what the human did, while the motion layer further determines how the robot itself should act.
The true value of this layer usually does not lie in the hardware itself; rather, its core function is to achieve more stable "motion translation."
The third category is the Robot-Native data layer, typically comprising third-party teleoperation and real-robot data service providers. The defining characteristic of these players is their close proximity to the robot hardware itself, often requiring deep integration with robotics companies.
Unlike other specialized data collection segments, real-robot data heavily depends on specific physical robots. Since hardware configurations, degrees of freedom, action spaces, and control interfaces vary significantly across different companies' robots, a single grasping task may need to be re-collected if switched to a different robot model.
During this process, they provide teleoperators, physical spaces, and real-world data collection capabilities, helping robotics companies rapidly accumulate training data. This is especially crucial during the early stages of model validation when robotics firms lack sufficient teams and facilities themselves; external service providers can often launch more quickly.
The fourth category consists of synthetic simulation data companies. They do not merely sell data but focus on building a more comprehensive data capability.
Their specific approach starts with simulation-based data generation, centering around simulation environments, evaluation systems, and closed-loop model feedback. They aim to infinitely scale up experiences from the real world. For instance, Guanglun Intelligence saw its new orders reach 550 million yuan in the first quarter of this year.
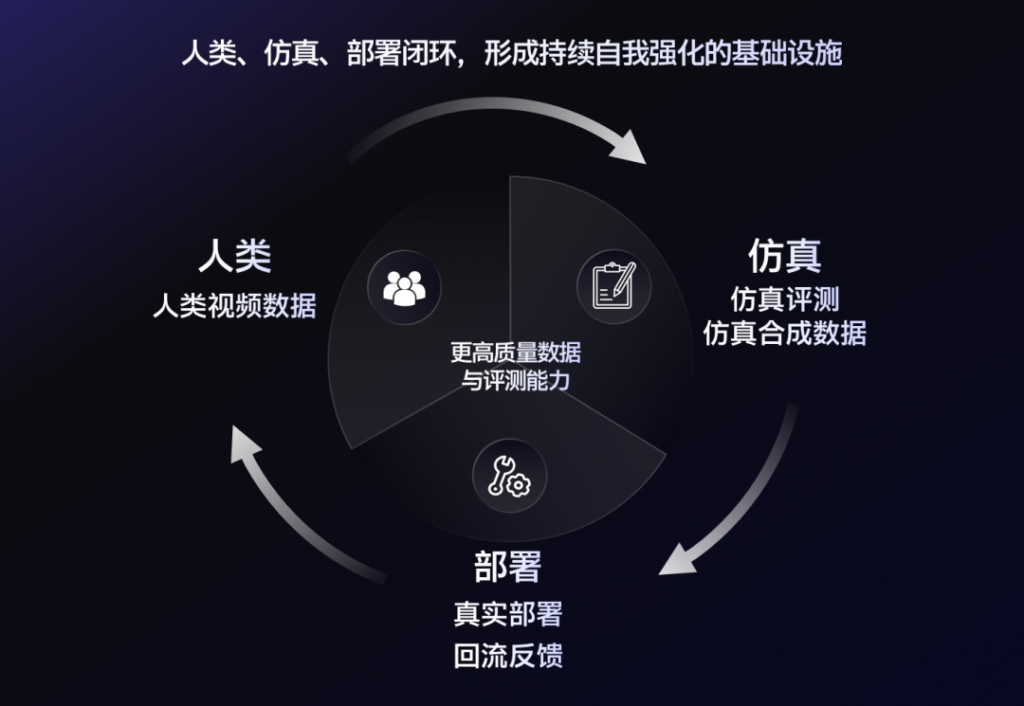
While producing data, these companies also help clients understand why tasks failed and determine how to collect the next batch of data—a new route many companies are currently pursuing.
The logic is straightforward: training a robot for a day might only yield a few hours of effective trajectory data. However, in a simulation world, within the same timeframe, the robot can fail millions of times—grasping failures, path planning errors, collisions, and falls can all be repeated infinitely.
Consequently, the industry is gradually forming a new combination strategy: real-world data serves to anchor reality, while synthetic simulation data drives scalable expansion.
NVIDIA has repeatedly emphasized in its GR00T roadmap that robot foundation models require not only human demonstration data but also substantial amounts of synthetic data. Developers can first acquire priors through real-world data collection and then leverage simulation to expand task scale.
The more a model fails in simulation, the clearer it becomes what data is missing, and whoever can produce that data fastest gains a competitive edge.
The fifth category of players leans toward the data standards and platform layer, seeking to make data supply itself more standardized and easier to circulate while expanding data scale.
As robotics companies proliferate, data has become highly fragmented: differing collection methods, motion representations, and format standards mean that identical datasets are often not directly reusable.
In this context, efforts toward embodied data standardization and collaborative collection have noticeably increased this year.
For instance, MiFeng Technology aims to unite different roles across the industry chain to explore more unified data collaboration, publicly targeting a data production capacity of tens of billions of hours by 2030.
For the current robotics industry, lacking data is only one problem; equally critical is whether data can be generated consistently and stably and integrated smoothly into training pipelines.
Nevertheless, whether dealing with human-collected data, real-robot data, or simulation-based data, all players must ultimately answer this question: Will robotics companies hand over these core capabilities to external suppliers?
After all, for most embodied AI companies today, data is not just a cost but also a competitive moat.
Should Robot Companies Buy Data or Collect It Themselves?
Data has become a pivotal asset in the robotics industry this year, with everyone acknowledging the sector's acute data shortage.
Compared to the past, the market now offers an increasing variety of data supply options. With suppliers available for different types of data, it is becoming increasingly easy for robot companies to purchase data.
However, the reality is somewhat different: while more and more robot companies are procuring data, leading firms are simultaneously working hard to build their own data teams.
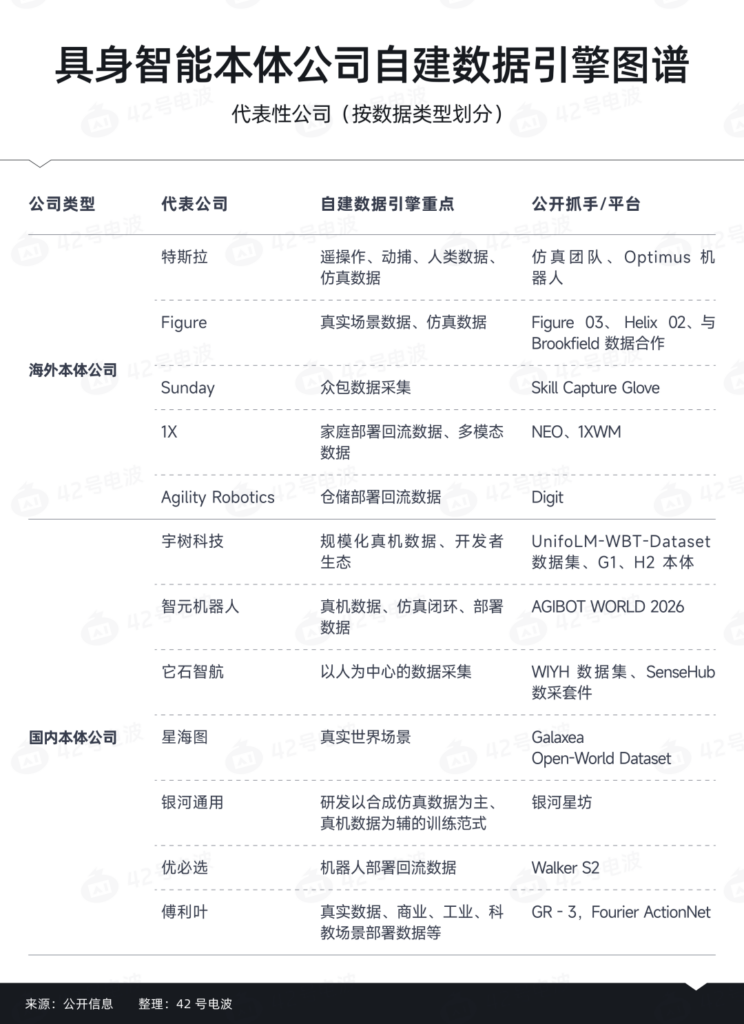
A deeper analysis reveals that different types of data dictate entirely different organizational structures.
In a sense, what has truly emerged among robot companies is a "layered procurement" logic.
The first layer consists of foundational general-purpose data, which is the most easily outsourced.
For example, behaviors such as kitchen organization, desk tidying, basic grasping, sorting, and moving share a common trait: regardless of a robot's form factor, it ultimately needs to understand how humans perform these tasks.
Consider a robot entering a kitchen: when should it free up one hand first? When should it organize larger objects before smaller ones? How does it replan spatially when there are too many items?
These capabilities essentially belong to general physical world cognition and are not exclusive to any single robotics company.
If a company were to collect Ego data like this from scratch, it would need to build a team, resulting in high management costs.
In contrast, external teams can rapidly scale data collection in regions like Southeast Asia and India, stably producing thousands of hours of data per month.
For robotics companies, purchasing such data is often more cost-effective than building an internal team. At this stage, the goal is not to make robots work reliably but to help them understand the world.
Therefore, outsourcing this type of data is reasonable and even a more efficient choice.
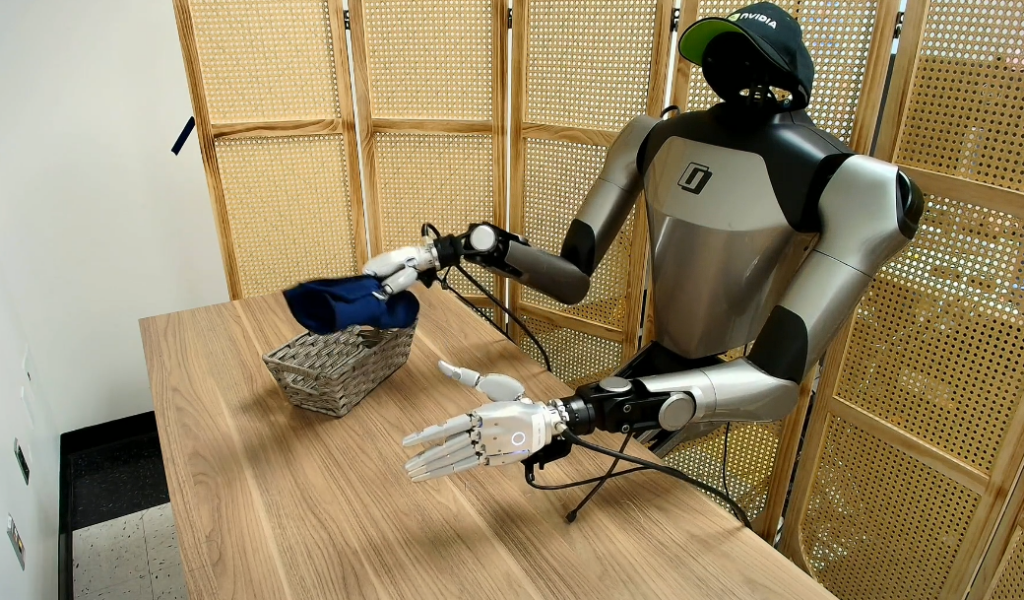
The second layer consists of Embodied AI adaptation data, which robot companies tend to collect themselves.
After pre-training on a large volume of foundational data, the training process begins to involve the core deployment aspect: task alignment.
This is where the logic shifts, as each company's robot hardware differs significantly in degrees of freedom, dexterous hands, joint capabilities, and other aspects. Consequently, the action logic robots ultimately need to learn varies greatly.
The closer the data is to the action execution layer, the less universal it becomes. Therefore, even though many companies purchase extensive Ego Data, they still build internal data collection teams to gather real-robot data. This layer is beginning to approach the model's true competitive edge.
The third layer comprises deployment data and failure data, a highly critical layer that typically emerges after actual deployment.
When robots are deployed in real-world application scenarios, they often encounter various unpredictable situations. The deployment data generated from these real environments—whether successful or failed—is extremely valuable and rarely encountered or designed for during preliminary data collection; it can only be accumulated incrementally in real-world settings.
Moreover, many companies struggle to deploy their robots extensively in real-world scenarios, making the acquisition of real deployment data difficult to achieve.
During deployment, robots accumulate data in dynamic environments; even failure data helps teams identify root causes and develop countermeasures to optimize models, thereby facilitating large-scale robot deployment.
These core datasets belong to leading robotics companies and form their competitive moat against rivals.
This somewhat caps the growth potential of specialized data companies: while they can help robots reach a baseline capability, the data that truly determines performance ceilings is often retained by major players themselves.
Thus, two distinct paths have emerged in the data industry: data factories and data engines.
Data factories are currently the fastest-growing and most numerous type of company, with the easiest path to generating cash flow.
Low-cost data factories prioritize human behavioral data, leveraging inexpensive labor to charge hourly fees and scale delivery capacity. While they may achieve positive cash flow quickly, their barriers to entry are low, and competitors—especially following EgoScale’s rise—are rapidly entering the human data space.
Higher-complexity data factories build on human behavioral data by deploying robots at scale, collecting large volumes of real-world operational data via teleoperation or autonomous body control.
The alternative path—the data engine—focuses on structuring task taxonomies, building data architectures, implementing motion retargeting, integrating simulation platforms, establishing model evaluation frameworks, and iteratively producing datasets using model failure cases.
In other words, what they are doing is not just selling data; the key focus is enabling robots to continuously become smarter.
Will a Robot Version of Scale AI Emerge?
Placing today's robotics industry back into the context of the large model era in 2022 reveals a striking similarity.
At that time, the industry also discovered that what truly determined the upper limit of a model's capabilities was data.
Consequently, a new wave of companies rapidly rose around areas such as data cleaning, RLHF (Reinforcement Learning from Human Feedback), evaluation, and post-training. The most classic example is Scale AI.
In its early stages, this company helped autonomous driving firms label data. Starting from 2019, during the GPT-2 phase, Scale AI formed deep ties with OpenAI, undertaking tasks such as human feedback labeling for RLHF, large model evaluation, red teaming, and reverse-generating data for edge cases.
After ChatGPT went viral, Meta Llama, Anthropic, Microsoft Azure, and others quickly integrated it. The demand from large models for high-quality annotation, evaluation, and synthetic data surged, causing the company's revenue to more than quadruple over three years.
Later, the company gradually moved into deeper layers of infrastructure, including data management, model evaluation, and AI workflows.
Inspired by Scale AI's success, many are wondering whether a similar company might emerge in the robotics industry.
Given the current severity of data shortages, this is highly likely, though it won't be an exact replication.
This is because the data required for robotics is far more complex than text; for large language models, determining whether an answer is correct or incorrect is relatively straightforward. However, in the world of robotics, whether an action succeeds is often ambiguous.
The cup was picked up, but at the wrong angle. The item was put back, but knocked over other objects. Moreover, there are often multiple correct paths to complete a task.
Therefore, what the robotics industry truly needs is not just a simple data platform, but a complete closed-loop system encompassing data collection, annotation, motion mapping, simulation-based augmentation, model evaluation, and failure feedback.
What robotics truly lacks is not merely data, but the ability to continuously produce effective experience.
Consequently, an increasing number of companies are shifting their competitive focus from robot hardware and model architectures toward data systems.
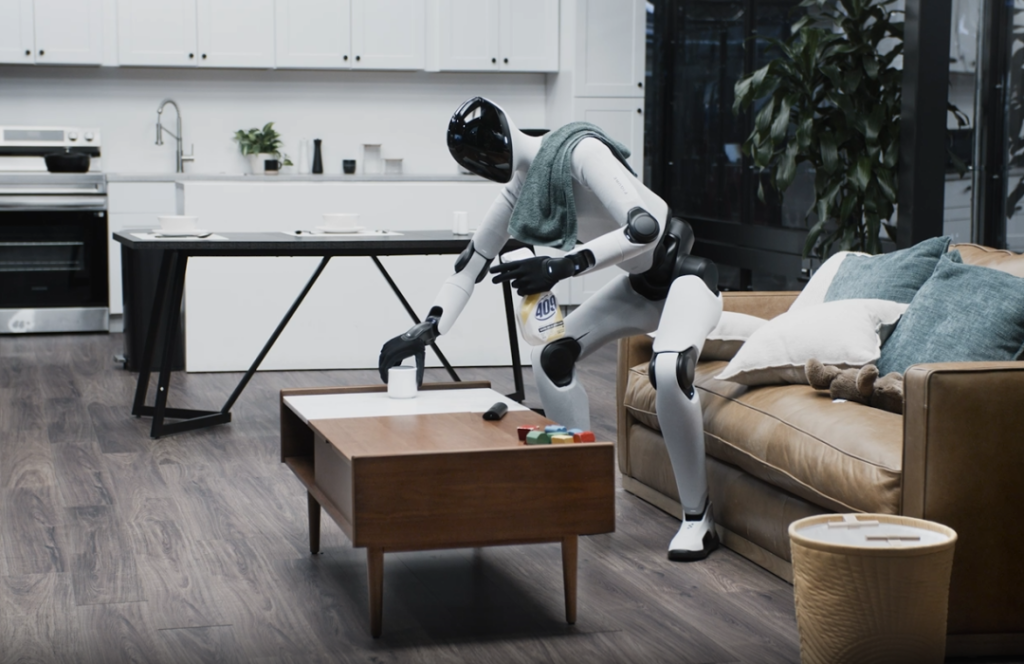
Since the beginning of this year, whether it is Figure, 1X, PI, or the GR00T initiative promoted by NVIDIA, all have repeatedly emphasized a common direction: the growth of robot capabilities relies not only on hardware upgrades but increasingly on data and more effective training.
To some extent, as the mass production and deployment phase of the robotics industry begins, we are transitioning from 'building robots' to 'feeding robots.'
In the early stages when robots could not stand or walk, the core competitiveness of embodied AI companies lay in their ability to perfect hardware and motion control.
But once robots can run and jump, achieving performance in various competitions that surpasses humans, autonomous operational capability becomes the industry's primary goal. Driven by this objective, the main focus shifts to large-scale, high-quality data.
For robots to achieve sustained success in complex real-world environments, they need to encounter enough physically realistic tasks—knowing that cups might spill, clothes might tangle, or spaces may be too tight. These experiences do not exist naturally on the internet; they must be produced incrementally.
Therefore, behind the recent surge in robotics enthusiasm, this data industry chain has quietly taken shape over the past two years.
At one end of the chain are humans wearing cameras in Indian factories, and robots that constantly fall during simulation.
At the other end are robot companies valued at hundreds of millions, billions, or even trillions of dollars, striving to bring robots into homes and factories.
From data factories in India to simulated robots and global robotics firms, a new production chain is emerging; however, this time, what is being produced is not components, but data.