
Behind the Unitree Controversy: NVIDIA's New Compute Business
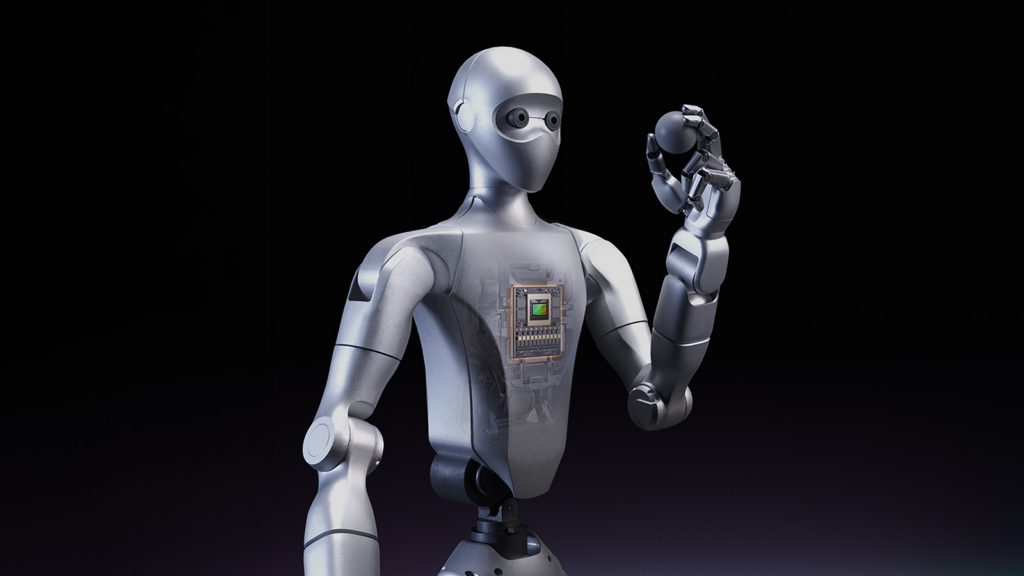
During GTC 2026, NVIDIA released the Isaac GR00T Reference Humanoid Robot for academic research. According to public information, this reference design uses the Unitree H2 Plus humanoid robot body, equipped with the NVIDIA Jetson AGX Thor computing platform, paired with Sharpa's five-finger dexterous hand, as well as the Isaac GR00T robot foundation model and development stack. The first batch of products is planned to be supplied to universities and research institutions.
At first glance, this appears to be a routine hardware collaboration: Nvidia provides the computing platform and software stack, while Unitree supplies the humanoid robot body. Together, they are launching a research reference platform.
But things quickly got complicated.
On one hand, Unitree nearly completed its approval for an IPO on the Science and Technology Innovation Board at almost the same time, with its prospectus explicitly stating that a large portion of funds would be directed toward the research and development of intelligent robot models and their physical bodies. The capital market naturally linked these two events: Unitree is not just a Chinese humanoid robot manufacturer but is also entering Nvidia's Physical AI ecosystem. On the other hand, regulatory discussions in the United States regarding Chinese robot products are intensifying. Bipartisan members of Congress have proposed the GUARD Act to require security agencies to review Chinese humanoid and quadruped robots, while the Department of Defense's List 1260H mandates restrictions on contracting and procurement. Such policy signals create higher uncertainty for Chinese robot companies like Unitree in the US market.
Unitree, at the center of the controversy, has been heavily criticized. However, focusing solely on Unitree can lead to an underestimation of the broader implications. For Nvidia, Unitree is neither its only partner nor irreplaceable. What it truly aims to validate is another matter: whether the robot era can replicate the success of the large model era by building a "CUDA ecosystem" for robot training, thereby sustaining its computing power business.
**Nvidia is Seeking the Physical Entry Point
Nvidia is unlikely to enter the humanoid robot manufacturing business itself, as this would contradict its past success path. In the era of large models, Nvidia is not OpenAI, Anthropic, or Google DeepMind, but these companies cannot avoid using GPUs, CUDA, NCCL, and TensorRT when training and deploying models. Nvidia has not occupied the model and application layers, but it dominates the underlying computing power layer and development ecosystem. The same applies to the robotics era.
Nvidia does not need to manufacture the most humanoid robots; instead, it aims to become a foundational platform supplier for the robotics industry. Different manufacturers can have different bodies: Unitree, Figure, Agility, Boston Dynamics, NEURA, etc., can all create their own mechanical structures, joints, motors, controllers, and complete products. However, once these bodies integrate with Isaac, GR00T, Cosmos, Jetson, and Newton, a significant portion of the computation in the robot training and deployment chain will return to Nvidia's platform. Therefore, Unitree's role in this matter is that of a body entry point. This entry point has two characteristics.
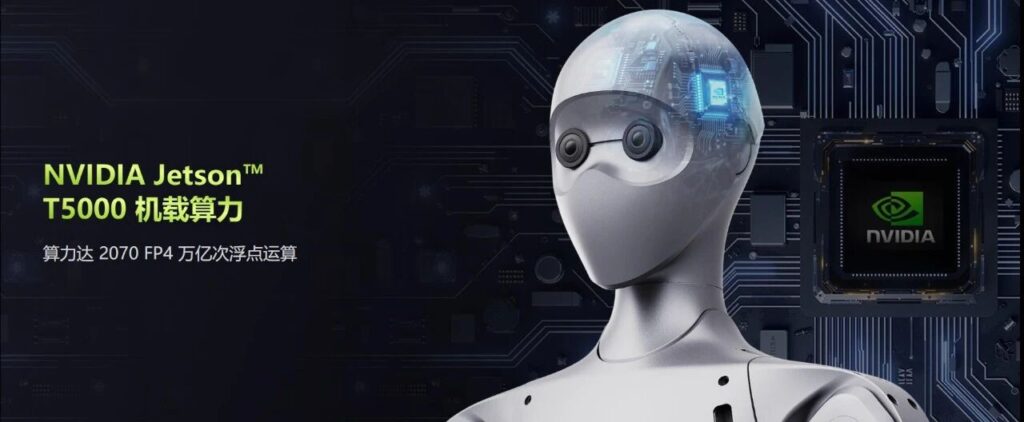
First, Unitree possesses cost and engineering advantages. Compared to many Western humanoid robot companies, Unitree is more adept at transforming complex robots into purchasable, deliverable, and iterable hardware products. According to the official website, the H2 Plus features the Jetson T5000 onboard computing module, achieving 75 degrees of freedom after pairing with dual Sharpa Wave dexterous hands, and targets research and secondary development scenarios.
Second, Unitree already has a researcher base. Products like G1, H1, and H2 have gained visibility among university students and developer communities. If Nvidia wants robot foundation models like GR00T to quickly enter laboratories, it needs an affordable, open, and expressive body platform. This is why Nvidia places reference designs first in academic research scenarios. Although the scientific research market may not be the largest, it influences standards. Papers, open-source code, benchmarks, and experimental paradigms often emerge from universities and research institutions. By allowing institutions such as Ai2, ETH Zurich, Stanford, and UCSD to use these reference designs first, Nvidia is essentially competing for the default development environment for robotics research. Defining standards is a key step in anchoring long-term markets; once standards are established, future robots will likely be deeply integrated with Nvidia's tech stack from the start.
What's Missing Is Not Just Bodies, But Data
Having bodies only solves the first layer of problems. The real challenge in robot training lies in data.
Large model training has a natural advantage: the Internet has accumulated massive amounts of text, images, and videos. Language models can learn language from what humans have written and learn world knowledge from web pages and videos.
But robots require real physical interaction actions. For example, how hands grasp cups, how feet find balance, how joints distribute torque, how to adjust paths when hitting table edges, and how to make corrections when objects slip.
More troublesome is that this robot motion data is inherently fragmented. Human videos are one format, motion capture data is another, teleoperation data is yet another, and simulation trajectories are a different format. Furthermore, different robot bodies vary in joint count, degrees of freedom, hand structures, and sensor configurations. A human raising their arm cannot be directly converted into control commands for a specific humanoid robot; an action learned by one robot cannot be directly transferred to another. Therefore, for robot pre-training to scale up, we must first solve the problem of 'how to represent motion.'
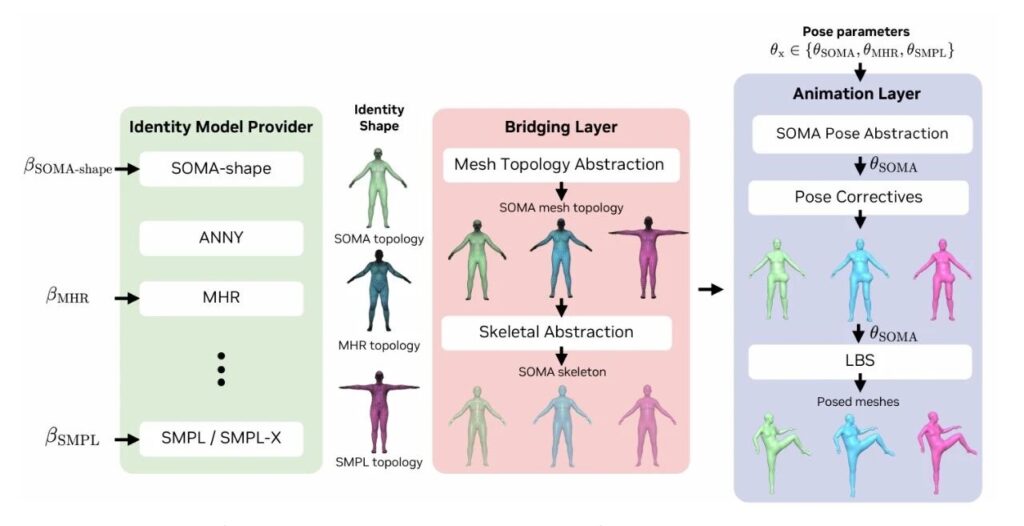
This is the significance of work like Nvidia's SOMA-X. It addresses incompatibility issues between different parametric human body models, such as differences in mesh topology, skeleton structure, shape parameters, and unit conventions among models like SMPL and SMPL-X. The paper proposes unifying meshes, skeletons, and pose abstractions so that different human body models and motion data can enter the same representation layer.
If robots are to learn human motions, they must first convert human motions into unified, computable, and transferable representations. Otherwise, more data leads to messier formats; larger models make it harder to converge to usable actions. From this perspective, robots need not only real physical bodies but also 'data bodies.'
The real physical body determines which machine ultimately executes the actions; the data body determines how actions are recorded, generated, transformed, and reused within the training system.
Isaac Newton Becomes the Embodied Training Ground
The name of Isaac Newton, father of modern physics, appears to have been integrated by NVIDIA into its robotics technology ecosystem: Isaac Lab handles the learning and training workflows for robots, while the Newton solver manages physical simulation and computation.
This may not necessarily be a deliberately designed naming strategy by NVIDIA, but as an industrial metaphor, it is highly accurate. The world robots face remains a Newtonian physical one. Gravity, friction, contact, collision, inertia, joint constraints, and torque limits do not disappear simply because model parameters grow larger. Language models can trial and error within token space, but robots must bear the consequences of their actions in the physical world. Therefore, action data alone is insufficient; movements must also be tested and refined within physical environments.
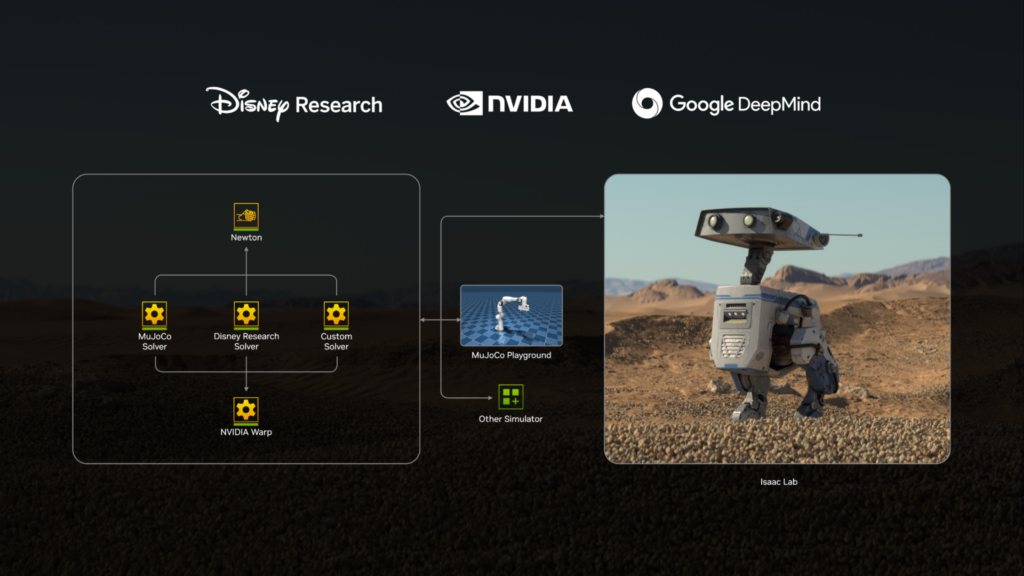
This is where Isaac Lab fits in. It is NVIDIA’s training framework for robotic learning, designed to organize reinforcement learning, imitation learning, motion control, and manipulation tasks. The latest direction for Isaac Lab 3.0 Beta is clear: multi-physics backends, pluggable renderers, Warp-native data pipelines, and kit-less installation modes. These changes indicate that Isaac Lab is evolving from a "training tool on Isaac Sim" into a more independent robotic training platform.
The Newton solver operates at a more fundamental level. It handles issues such as collision, contact, joints, friction, constraints, and differentiable physics. Newton v1.3.0, released in June 2026, added and enhanced capabilities including solver reset for reinforcement learning, SDF/hydroelastic collision detection, ray queries, USD/MJCF asset import, and viewer/rendering functions. While these features may not be suitable for press conference hype, they determine whether robotic training can be successfully engineered.
If SOMA-X addresses how to unify the representation of actions, Isaac Lab and Newton solve how these actions are trained, validated, and optimized under physical rules. Because the greatest challenge in the robotics industry is not making simulated videos look impressive, but ensuring that policies trained in simulation still work on real hardware. The gap between simulation and reality is the hard problem of Physical AI.
It is precisely in this sense that the metaphor behind the name Isaac Newton holds true. What NVIDIA aims to do is not equip robots with a chat model, but build a "physics school" for them: first turning actions into data, then placing that data into simulations, allowing policies to experience sufficient physical consequences in the virtual world, and finally transferring them to real-world embodiments.
Nvidia's Robot Training Stack Is Taking Shape
Putting these components together reveals Nvidia’s actual technology stack, which spans the entire robot training pipeline.
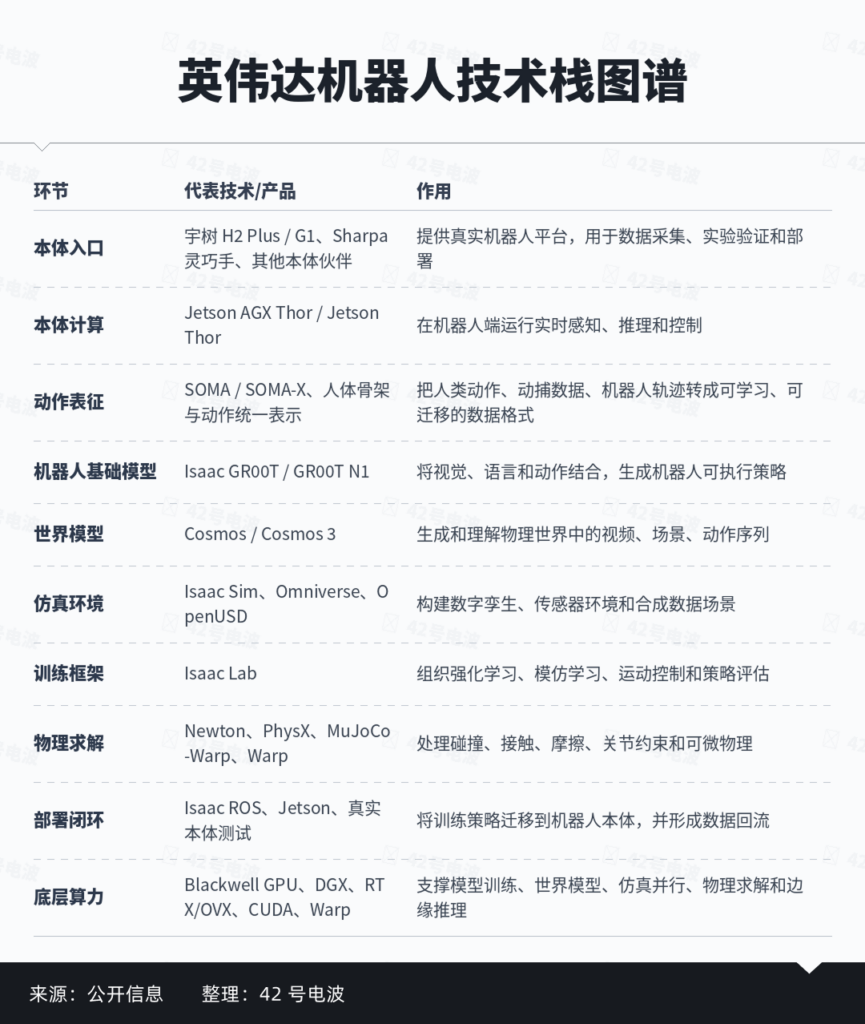
The hardware provides real-world embodiment, action representations supply data formats, GR00T connects perception to action, Cosmos supplements world models and synthetic data, Isaac Sim offers a simulation environment, Isaac Lab orchestrates training, Newton handles physics, Jetson manages deployment, and everything ultimately relies on GPUs and CUDA at the base.
This is Nvidia’s familiar business model. It may not own end-user applications, but it aims to control the development pathway. As long as the development path is defined by Nvidia, industry progress will drive computing demand back to its platform.
Physical AI Is the Narrative; The Essence Returns to Computing Power
Nvidia excels at creating concepts. Terms like AI Factory, Omniverse, Digital Twin, Physical AI, World Foundation Model, and World Action Model all carry Huang Jen-hsun's distinctive narrative style. They are grand, smooth, and convincing enough for investors and developers to believe that the next wave of innovation is on the horizon.
But if we put it more directly, Nvidia is still doing what it does best: transforming the next technical challenge into the next demand for computing power. In the era of large models, GPU demand comes from tokens. As models need to read more text, generate more content, and process larger contexts, they require more training and inference computing power. In the era of robots, GPU demand will come from actions. Behind a single action lies not just a movement command; it requires perception input, language understanding, action generation, physical simulation, policy training, failure replay, real-world embodiment validation, and edge-device real-time control. Every step in this chain demands computing power.
Nvidia’s GR00T N1 technical report, 'An Open Foundation Model for Generalist Humanoid Robots,' shows that training such robot foundation models uses a mixed dataset of real robot trajectories, human videos, and synthetic data. It employs a vision-language-action architecture to connect understanding with action generation.
Cosmos 3 goes a step further by integrating language, images, video, audio, and action sequences into a unified world model framework to serve Physical AI. The more complex the actions, the more simulations are needed; the more simulations there are, the greater the GPU consumption; and the higher the GPU consumption, the more stable Nvidia’s business becomes. Nvidia aims to extend the compute narrative of AI from tokens to actions. Just as Newton abstracted the physical world into calculable laws decades ago...
...Nvidia today seeks to abstract robotic actions into trainable computing processes. From human movements to unified representations, from unified representations to simulation-based training, from simulation training to real-world embodiments, and from real-world embodiments back to data回流 (feedback). Each step is being software-ized, platform-ized, and GPU-ized.
This is not merely a robotics story; it is Nvidia’s strategic layout to push computing growth from the linguistic world into the physical world. Unitree provides a sufficiently concrete embodiment sample, making this narrative tangible for the first time; work like SOMA-X provides a unified entry point for action data; Isaac Lab and Newton train actions within physical simulations; while Cosmos and GR00T connect world models with robot foundation models.
Ultimately, all these efforts return to the same question: as robots multiply, so do actions, simulations, and training needs—who will provide the computing power? Nvidia has already given its answer. It doesn’t necessarily have to build robots itself, but it must ensure that robots become a new source of computing business.